
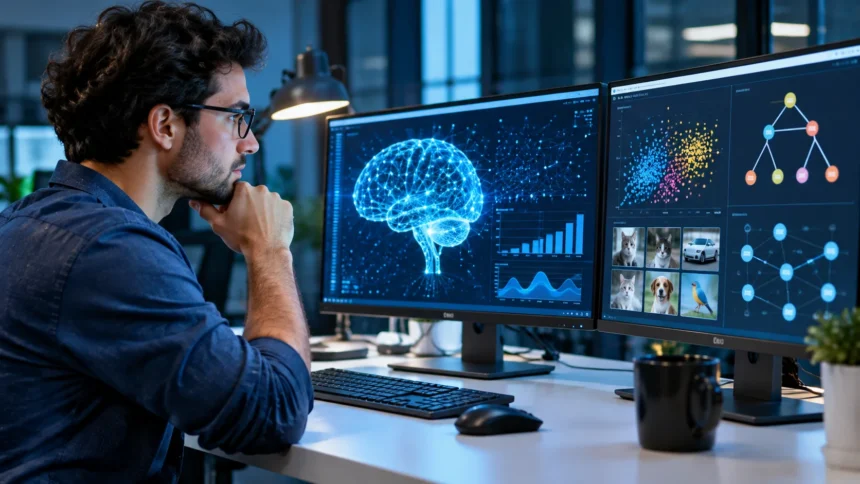
Machine learning is one of the most important technologies behind many modern digital tools. From personalized recommendations and voice assistants to fraud detection and medical research, machine learning helps computers identify patterns and make useful predictions. Understanding machine learning basics can help beginners recognize how these systems work and why they are becoming increasingly important.
Unlike traditional computer programs that rely entirely on explicitly written instructions, many machine learning systems learn patterns from examples. They analyze information, identify relationships, and use those patterns to process new data. This approach makes machine learning useful for tasks that are difficult to solve with a fixed collection of rules.
However, machine learning is not magic, and computers do not automatically understand information the way humans do. Their performance depends on training data, mathematical models, testing, and careful human supervision. This guide explains what machine learning means, how it works, its major types, practical applications, benefits, challenges, and important concepts every beginner should understand.
What Is Machine Learning?
Machine learning is a branch of artificial intelligence that focuses on developing computer systems capable of learning patterns from data. Instead of requiring programmers to write every rule manually, machine learning algorithms use examples to identify relationships. These learned patterns help systems make predictions, classify information, or perform other specific tasks.
For example, an email application can use machine learning to identify messages that are likely to be spam. The system learns from examples of unwanted and legitimate emails rather than relying only on predefined keywords. As it processes new messages, it uses previously learned relationships to estimate which category each email belongs to.
Machine learning is already present in many familiar technologies, including search engines, recommendation platforms, and navigation applications. Although these systems perform different tasks, they share a fundamental principle: using data to build models that support automated decisions. Understanding this basic concept provides a foundation for exploring more advanced machine learning topics.
How Does Machine Learning Work?
Machine learning generally begins with collecting information related to a specific problem. This information is called data and may include numbers, images, text, audio, or other digital records. Developers prepare the data before using a machine learning algorithm to identify useful patterns within it.
During training, the algorithm adjusts a mathematical model based on the examples it receives. The goal is to improve performance on a particular task, such as predicting prices or recognizing images. Different algorithms use different mathematical techniques, but they all aim to develop relationships that can be applied to previously unseen information.
After training, the model is evaluated using suitable testing data to measure its performance. If the results are satisfactory, it may be integrated into an application where it processes new inputs. Developers continue monitoring performance because changes in real-world conditions can affect how accurately a trained model works.
Why Is Machine Learning Important?
Machine learning is important because it allows computers to analyze large amounts of information and identify patterns that may be difficult to recognize manually. Businesses, researchers, and public organizations use these capabilities to support decisions and improve existing processes. The technology can be particularly valuable when information changes frequently or contains complex relationships.
Another advantage is the ability to automate selected tasks that previously required extensive manual analysis. For example, machine learning models can categorize documents, identify unusual transactions, and estimate future demand. When these systems are appropriately designed, they may save time and help professionals focus on work requiring human judgment.
Machine learning also supports scientific research and technological development across several industries. Researchers use it to study complex datasets, investigate relationships, and develop predictive tools. However, its usefulness depends on reliable information, suitable methods, and careful evaluation rather than simply applying an algorithm to every available problem.
Understanding the Main Types of Machine Learning
Machine learning is commonly divided into three broad categories: supervised learning, unsupervised learning, and reinforcement learning. Each category uses a different approach to learning from information or experience. Understanding these differences helps beginners recognize why particular algorithms are selected for different tasks.
Supervised learning uses labeled examples to teach models relationships between inputs and known outputs. Unsupervised learning examines data without predetermined target labels to identify patterns or structure. Reinforcement learning involves an agent learning through interactions with an environment and feedback related to its actions.
These categories are useful introductions, but real-world systems can combine multiple techniques. Other approaches, including self-supervised and semi-supervised learning, are also important in modern AI development. The best method depends on the problem, available data, desired output, and practical requirements of the application.
What Is Supervised Machine Learning?
Supervised learning is a machine learning approach that uses examples with known answers or labels. During training, the model examines input information alongside the expected output. It then learns relationships that help it make predictions when presented with new examples.
For instance, a supervised learning model might be trained using historical housing information that includes property characteristics and selling prices. The model learns associations between features such as size, location, and price. After training, it can estimate the value of another property based on similar available information.
Common supervised learning tasks include classification and regression. Classification predicts categories, such as whether an email is spam, while regression estimates numerical values, such as a house price. The quality of supervised learning depends heavily on accurate labels, representative examples, and appropriate model evaluation.
What Is Unsupervised Machine Learning?
Unsupervised learning analyzes information without being provided with a specific correct answer for each example. Instead, the algorithm attempts to identify patterns, similarities, or underlying structures within the data. This approach is useful when organizations want to explore datasets without already knowing every meaningful relationship.
One common unsupervised learning technique is clustering, which groups similar observations together. For example, a retailer might examine customer purchasing behavior to identify groups with shared interests. These groups may help analysts understand broad patterns, although the model does not automatically explain what those patterns mean.
Another important technique is dimensionality reduction, which simplifies complex datasets while preserving selected information. This can help researchers visualize relationships or prepare data for further analysis. Unsupervised learning results still require careful interpretation because identified patterns are not necessarily meaningful, reliable, or connected to causes.
What Is Reinforcement Learning?
Reinforcement learning is a machine learning approach in which an agent learns through interactions with an environment. The agent selects actions and receives feedback based on the results. Over time, it attempts to develop a strategy that maximizes an established reward signal.
A common educational example involves a computer agent learning to navigate a simulated environment. The agent receives feedback when its actions move it closer to a defined objective. By exploring different choices, it can gradually improve its approach without receiving a complete set of correct instructions beforehand.
Reinforcement learning is used in research involving robotics, simulated environments, and certain optimization problems. However, designing suitable rewards and ensuring safe behavior can be challenging. A system that maximizes its programmed reward does not necessarily understand broader human goals, making careful design and evaluation essential.
Machine Learning vs. Artificial Intelligence
Artificial intelligence is the broader field focused on developing systems capable of performing tasks associated with human intelligence. These tasks include reasoning, language processing, perception, and decision support. Machine learning is one approach within AI that enables systems to develop patterns and capabilities using data.
Not every artificial intelligence system relies entirely on machine learning. Some AI approaches use manually defined rules, search techniques, logical reasoning, or combinations of different methods. Machine learning, however, has become especially important because it supports many modern systems that process complex information.
For example, a rule-based program might classify messages using a predefined list of suspicious phrases. A machine learning system could learn patterns from many labeled email examples instead. Both approaches can support automated decisions, but they differ in how their decision-making behavior is established.
Machine Learning vs. Deep Learning
Deep learning is a specialized area of machine learning that uses artificial neural networks with multiple processing layers. These networks can learn complex representations from data and are especially useful for certain image, speech, and language tasks. Deep learning systems often require substantial computational resources, depending on their size and purpose.
Traditional machine learning algorithms may work well with smaller structured datasets and carefully selected input features. Deep learning models can often learn useful representations directly from larger collections of raw information. However, deep learning is not automatically better for every problem, especially when computational efficiency or interpretability matters.
For example, a simple decision tree may be suitable for analyzing a limited business dataset. A large neural network may be more appropriate for advanced image recognition or language generation tasks. Selecting between these approaches requires considering data availability, model performance, operational costs, and the need to explain predictions.
What Are Machine Learning Algorithms?
Machine learning algorithms are mathematical and computational procedures used to develop models from data. Different algorithms identify relationships in different ways, which affects their strengths and limitations. Some are designed for classification, while others support numerical prediction, clustering, or sequential decision-making.
Common algorithms include linear regression, logistic regression, decision trees, random forests, and support vector machines. Neural networks are another important family of machine learning models. Each approach has particular assumptions and practical requirements that influence when it performs effectively.
Beginners do not need to master the mathematics behind every algorithm immediately. A useful starting point is understanding what problem an algorithm solves and what type of information it requires. As knowledge develops, learning about model training, evaluation metrics, and algorithm selection provides a stronger technical foundation.
What Is Training Data in Machine Learning?
Training data is the collection of examples used to develop a machine learning model. Depending on the task, this information may contain customer records, numerical measurements, written documents, photographs, or other digital material. The model uses these examples to identify relationships relevant to its intended purpose.
Good training data should be relevant, sufficiently representative, and suitable for the problem being addressed. Incorrect labels, missing values, and unbalanced examples can reduce model reliability. In some situations, data may also contain historical biases that influence automated predictions or decisions.
Developers often divide available information into training, validation, and testing datasets. Training data helps the model learn, validation data supports model selection and adjustments, and testing data evaluates performance on held-out examples. Maintaining appropriate separation between these datasets helps produce more trustworthy estimates of real-world performance.
What Are Features and Labels?
Features are the input characteristics that a machine learning model uses to identify patterns. For a housing price prediction system, features might include property size, age, location, and number of rooms. These variables provide information the model can use when estimating an output.
Labels are the known answers associated with examples in supervised learning. In a housing dataset, the selling price could be the label used during training. The algorithm examines the relationship between property features and prices to develop a model capable of making predictions.
Not every machine learning task requires labels because unsupervised methods work differently. However, understanding features and labels is essential for recognizing how supervised learning operates. Choosing informative features, checking data quality, and preventing inappropriate information leakage can significantly influence model performance.
What Are Classification and Regression?
Classification and regression are two important types of supervised machine learning tasks. Classification predicts categories, while regression estimates numerical values. Both approaches use patterns learned from labeled examples to generate outputs for new information.
An email spam detection system is a classification example because it predicts whether a message belongs to a particular category. A model estimating monthly electricity consumption is a regression example because it predicts a numerical quantity. Although these tasks may use some of the same algorithms, their outputs and evaluation methods differ.
Classification systems may be evaluated using accuracy, precision, recall, and other suitable metrics. Regression models often use measures that describe how far predictions differ from actual values. Choosing the right evaluation method depends on the consequences of errors and the specific goals of the application.
What Is Overfitting in Machine Learning?
Overfitting happens when a machine learning model learns training examples too closely and performs poorly on new information. Instead of identifying relationships that generalize well, the model may capture noise or details that are specific to its training dataset. This can make training performance appear impressive while real-world results remain disappointing.
For example, a model might predict outcomes accurately for the examples it has already encountered. However, its performance may decline significantly when presented with unfamiliar cases. This difference suggests that the model has not learned patterns that transfer effectively beyond its original training information.
Developers use techniques such as regularization, cross-validation, and suitable model complexity to reduce overfitting. Obtaining representative data and evaluating performance on separate examples are also important. The goal is not simply to maximize training accuracy but to develop a model that performs reliably under realistic conditions.
What Is Underfitting in Machine Learning?
Underfitting occurs when a model is too limited or insufficiently trained to capture important relationships within the data. As a result, it may perform poorly on both training examples and new information. This problem can arise when the model is overly simple or lacks the information needed to solve the task.
Imagine using a very basic mathematical relationship to predict a complicated outcome influenced by several interacting factors. The model may miss important patterns because its structure cannot represent them adequately. Even when supplied with more examples, an unsuitable model may struggle to produce reliable predictions.
Addressing underfitting may involve selecting a more appropriate algorithm, improving features, or adjusting training procedures. However, increasing complexity without careful evaluation can introduce other problems, including overfitting. Effective machine learning involves balancing model flexibility with the ability to generalize beyond training data.
Real-World Applications of Machine Learning
Machine learning is used across industries to support activities involving complex information and repeated decisions. In healthcare, certain systems assist with medical image analysis and research. Financial institutions use machine learning for fraud detection, while transportation platforms apply predictive models to traffic estimation and route planning.
E-commerce platforms use recommendation algorithms to suggest products based on relevant browsing and purchasing patterns. Businesses may also apply machine learning to forecast demand, categorize customer requests, and identify operational problems. These applications demonstrate how predictive models can support both everyday services and specialized professional workflows.
Machine learning is also important in language processing, computer vision, cybersecurity, and scientific research. However, performance varies depending on the task, model, and available data. Organizations should evaluate practical results carefully rather than assuming that machine learning automatically improves every process where it is introduced.
Benefits of Machine Learning
One major benefit of machine learning is its ability to analyze large datasets and identify useful relationships. These capabilities can support faster information processing and reduce time spent on certain repetitive activities. When implemented appropriately, machine learning may improve efficiency and help professionals focus on tasks requiring human judgment.
Another advantage is the ability to develop predictive systems that respond to changing information. For example, forecasting models can support inventory planning, while classification tools help organize documents. Some systems can also be updated using new training data when their original patterns become less relevant.
Machine learning can support more personalized digital experiences through recommendation systems and adaptive software. However, its benefits depend on reliable implementation, suitable performance measurements, and responsible data handling. The technology provides the greatest value when it addresses a clearly defined problem and produces measurable improvements.
Challenges and Limitations of Machine Learning
Machine learning systems depend heavily on the quality and suitability of their training data. Incomplete, outdated, or biased datasets can lead to inaccurate predictions and unfair outcomes. Even technically advanced models may perform poorly when the information used during development does not reflect real-world conditions.
Another challenge involves understanding how certain models generate their outputs. Complex neural networks can be difficult to interpret, particularly when they contain large numbers of parameters. This creates additional concerns in sensitive areas such as healthcare, employment, and financial services, where decisions may require clear explanations.
Privacy, computational costs, security, and ongoing maintenance also affect machine learning projects. Models can become less reliable when underlying data patterns change over time. Organizations therefore need suitable monitoring, periodic evaluation, and human oversight to maintain safe and effective use.
How to Start Learning Machine Learning as a Beginner
Beginners can start learning machine learning by building a basic understanding of data, algorithms, and model evaluation. Familiarity with Python programming is especially useful because many educational resources and practical tools use this language. Basic knowledge of statistics, probability, and algebra also makes machine learning concepts easier to understand.
A practical learning path includes studying supervised learning before moving into more advanced methods. Small projects, such as classifying simple datasets or predicting numerical values, provide opportunities to apply theoretical ideas. Working with manageable examples helps beginners understand data preparation, training, testing, and common modeling mistakes.
It is important to focus on understanding results rather than simply copying code from tutorials. Ask why a particular algorithm was selected, how performance was measured, and what limitations the dataset introduces. This approach develops stronger problem-solving skills and prepares learners for increasingly complex machine learning applications.
Popular Tools and Technologies Used in Machine Learning
Python is widely used in machine learning because it provides accessible programming features and an extensive collection of specialized libraries. Common tools include scikit-learn for traditional machine learning methods and PyTorch or TensorFlow for developing neural networks. These technologies support different stages of model creation, training, and evaluation.
Data analysis libraries such as pandas and NumPy are also useful for preparing and organizing information. Visualization tools can help developers explore datasets and understand relationships before selecting an algorithm. Together, these technologies provide a practical environment for experimenting with machine learning concepts.
Beginners should avoid feeling pressured to learn every available tool immediately. Starting with Python, basic data analysis, and scikit-learn is often sufficient for introductory projects. As experience grows, exploring deep learning frameworks and deployment technologies becomes easier because the underlying machine learning principles remain relevant.
The Future of Machine Learning
Machine learning continues to develop as researchers improve algorithms, computational systems, and training methods. Advances in language models, computer vision, and multimodal learning are expanding the types of information AI systems can process. These developments may support more capable digital assistants, scientific tools, and specialized business applications.
Researchers are also exploring ways to improve model efficiency, reliability, and transparency. Smaller models designed for specific tasks may provide useful performance without requiring the resources associated with very large systems. Techniques that protect privacy and support safer deployment are another important area of continued development.
Despite ongoing progress, machine learning will continue to face challenges involving data quality, fairness, accuracy, and human accountability. The most valuable applications will be those that solve real problems while respecting practical limitations. Understanding the fundamentals today provides a useful foundation for following future developments in this rapidly evolving field.
Conclusion
Machine learning is a powerful area of artificial intelligence that enables computers to identify patterns and develop predictive capabilities using data. Its major approaches include supervised learning, unsupervised learning, and reinforcement learning. Understanding these categories provides an accessible starting point for exploring the technology behind many modern digital services.
The fundamentals of machine learning involve more than choosing an algorithm and training a model. Data quality, suitable evaluation methods, and awareness of limitations are equally important. Concepts such as features, labels, classification, regression, overfitting, and underfitting help explain how models are developed and why their performance may vary.
Learning machine learning basics does not require mastering every technical detail immediately. Beginners can build knowledge gradually through simple explanations, programming practice, and small projects. With a strong understanding of the core principles, it becomes easier to explore advanced topics and recognize how machine learning can be used responsibly in real-world situations.
Frequently Asked Questions
What is machine learning in simple words?
Machine learning is a technology that allows computers to learn patterns from data and use those patterns to make predictions or decisions. It is commonly used in recommendations, image recognition, and fraud detection.
What are the three main types of machine learning?
The three main types are supervised learning, unsupervised learning, and reinforcement learning. They differ in how models receive information, identify patterns, and improve their performance on specific tasks.
Is machine learning the same as artificial intelligence?
No, machine learning is a branch of artificial intelligence. AI includes several approaches to creating intelligent systems, while machine learning specifically focuses on developing models that learn patterns from data.
Do beginners need coding skills to learn machine learning?
Coding is not necessary for understanding basic concepts, but programming skills become useful for practical projects. Python is a common starting language because of its accessible syntax and machine learning libraries.
What is the best way to start learning machine learning?
Start by understanding basic concepts, learning introductory Python, and exploring simple datasets. Practice supervised learning projects, study model evaluation, and gradually progress toward more advanced algorithms and applications.